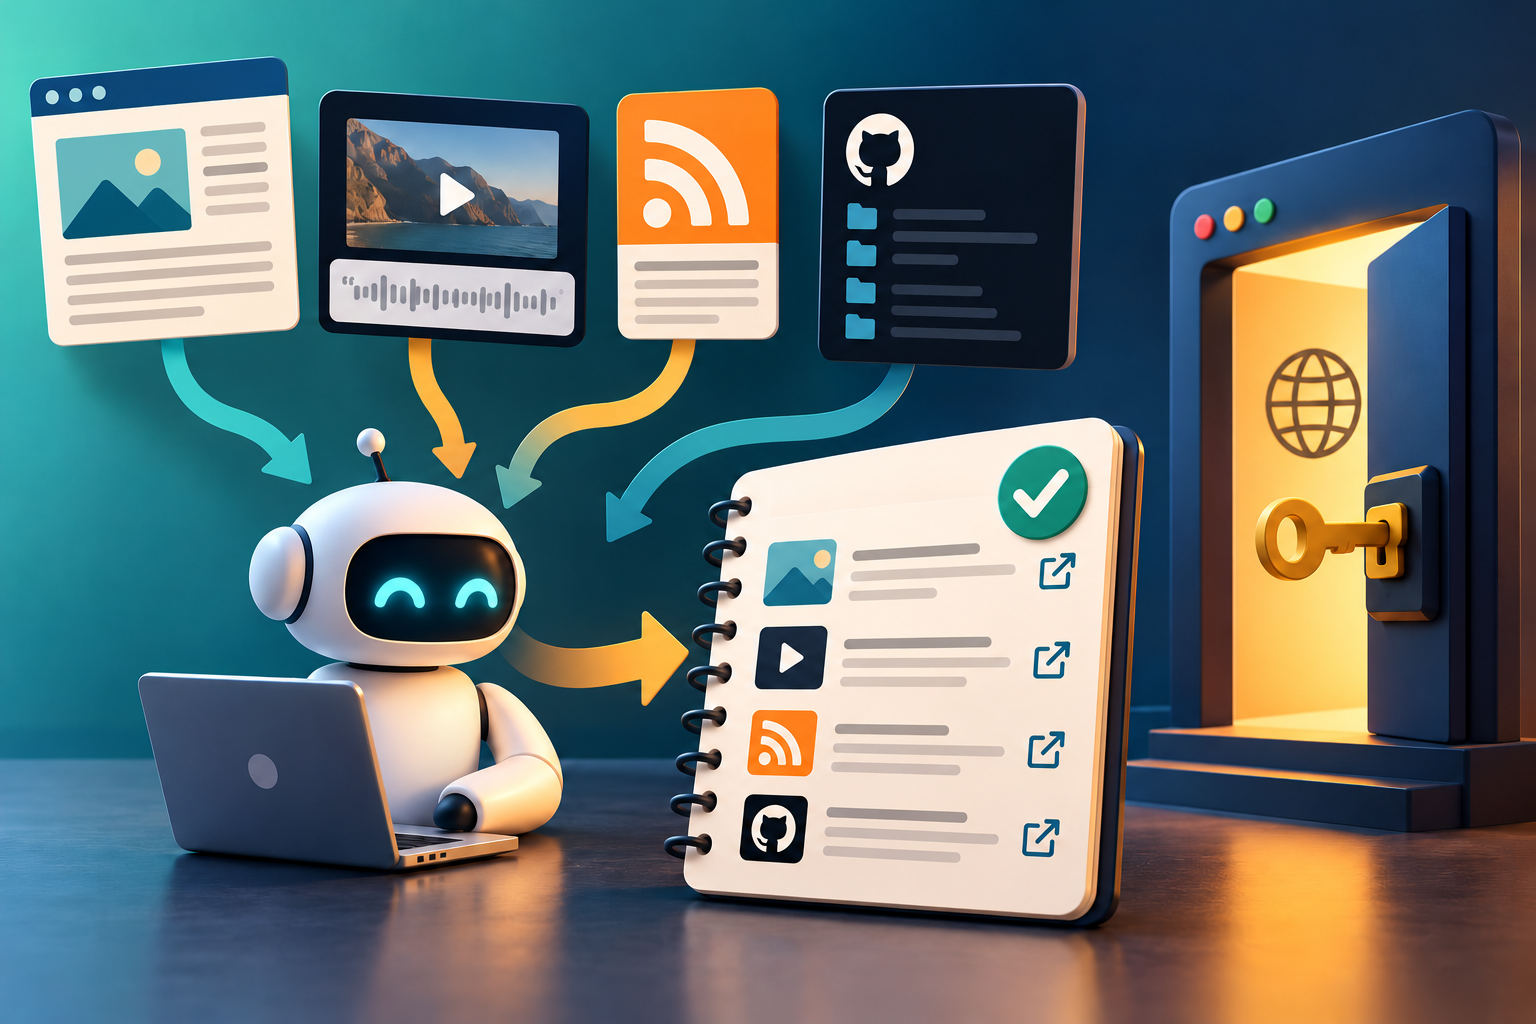
Original editorial illustration; this is not a real product screenshot, laboratory photograph or clinical result.
Agent Reach is today's emerging-tool discovery, not a claim of a new launch on 8 October 2026. The public MIT-licensed repository describes a capability layer that helps AI agents read and search internet sources through existing tools. It is not a new language model, a training dataset, or one universal official API. Its practical appeal is making research channels easier to configure and diagnose while leaving the reasoning agent and its model as separate choices. Official repository and documentation, reviewed 8 October 2026.
For marketers, the interesting question is whether the tool can produce a more reliable source notebook with less repetitive setup. A demo that collects many links is not enough. The system must preserve where information came from, identify failures, distinguish dates, and leave publication decisions under human review. A useful pilot therefore measures evidence quality alongside time saved, not just the number of websites the agent can access.
Understand what the project actually supplies
The repository presents Agent Reach as a setup, routing, and diagnostic layer around upstream readers and search tools. Listed examples include Jina Reader for public webpages, yt-dlp for YouTube workflows, feedparser for RSS, and the GitHub command-line client for repository access. Other channels need additional components or authentication. The project is not a promise that every source will work immediately without configuration. Current capability documentation.
That architecture has an important consequence: reliability depends on both the layer and its dependencies. If a source changes its page, a third-party reader fails, or an account permission expires, the research workflow can break even though the main project still runs. Record which backend produced each result. Otherwise, troubleshooting becomes guesswork, and a failure may be mistaken for evidence that the information does not exist.
Separate access, extraction, and interpretation
Access means the agent can reach a source. Extraction means it can retrieve the relevant text, transcript, or structured record. Interpretation means it can understand the material and produce a defensible conclusion. Success at one stage does not establish success at the next. An accessible page may omit content loaded elsewhere, and an extracted transcript may misrepresent a technical term.
Design the workflow so each stage is inspectable. Keep the original URL, retrieval time, extracted material, and any warning about completeness. Ask the agent to distinguish direct source facts from its own inference. A marketing analyst can then check whether the conclusion follows from the source rather than trusting an attractive summary. This separation is especially important when the final material will become a public article or advice to a client.
Start with public research channels
For a first pilot, choose sources that do not require personal login: official product announcements, public documentation, repositories, and available RSS feeds. Define a small research question, such as identifying material changes to advertising measurement tools. Give the agent a source list and ask it to produce an evidence table, not a publish-ready article on the first pass.
The table should contain the development, event date, publication date, original link, short supporting evidence, availability, and unresolved questions. These fields help prevent a common research error: treating newly discovered old documentation as a fresh announcement. A public-source pilot also makes the output easier to audit because another reviewer can open the same links without needing access to a private account or authenticated session.
Run diagnostics before trusting a channel
The documented doctor workflow tests available backends and reports channel readiness. Treat that output as a starting point for validation, not a permanent guarantee. A successful test today can be followed by a changed page, rate limit, or blocked source tomorrow. Keep the diagnostic result with the pilot record so the team knows what was functioning when the research ran. Repository diagnostic instructions.
Test representative tasks rather than only checking that a command exists. Can the channel read an official announcement, retain its date, and preserve the destination link? Can it detect a failed retrieval instead of inventing a summary? Does a fallback return equivalent evidence or merely different text? Those checks make the channel's practical limitations visible before it becomes a hidden dependency in daily content production.
Install deliberately and preserve the environment
The repository distinguishes ordinary installation checks from explicitly requested system-level changes and offers a dry-run path. Review the current instructions before installation, and verify the repository source rather than assuming a similarly named package is equivalent. The article does not require installing the project into a production publishing environment. Official installation guidance.
Use an isolated test environment with recorded dependency versions. Inspect proposed changes before granting additional privileges. Keep the pilot separate from the live website build until its behavior is understood. A research tool can be valuable without receiving access to deployment credentials, business accounts, or private health records. Limiting that scope also makes rollback simpler if a dependency proves unreliable or unsuitable for the organization's operating requirements.
Authentication changes the risk and responsibility
Some channels rely on browser sessions, cookies, or other authenticated access. Such access can represent the user's account authority, not just permission to read a public webpage. Decide whether the channel is necessary and whether the account is appropriate for the task. A dedicated research profile can make permissions easier to understand than a personal profile containing unrelated services.
Do not interpret a project's local credential-storage claim as an independent security audit. Review what each dependency can access, where credentials are stored, and how they can be revoked. Avoid transferring sessions to a tool merely to increase its channel count. The business objective should justify the access. Public-source research is often enough for product monitoring and competitive evidence, particularly when the final output should be independently verifiable.
Keep the model and costs explicit
Agent Reach does not eliminate the need to choose a reasoning model or pay for unrelated infrastructure. The agent may use a commercial model, local compute, search services, or other providers depending on the configuration. A project description emphasizing low API fees does not establish zero total operating cost.
Record model usage, search charges where applicable, hosting, maintenance, human review, and troubleshooting. Measure the total cost of producing an accepted research output. A workflow that retrieves more material but requires extensive correction may be more expensive than a simpler process. Conversely, a reliable public-source workflow can be useful even with some provider costs if it saves repeated setup and improves the team's ability to verify sources consistently.
Build a reviewable source notebook
Give every factual claim a source entry and separate confirmed facts from open questions. Preserve exact dates and versions where material. Avoid storing only the model's summary, because the reviewer then loses the evidence needed to assess it. A source notebook should make it easy to revisit the original material when a platform updates its documentation.
For a daily briefing, add a record of previously covered stories and the material new development required for repetition. That prevents the system from selecting the same useful but unchanged announcement again. A repository discovered today should be labeled as a discovery unless its release history supports a launch claim. The notebook becomes an editorial asset: it helps the team choose stories, track corrections, and distinguish evidence from recommendations.
Treat retrieved content as evidence, not instructions
Webpages and repositories can contain text aimed at influencing an agent's behavior. The research workflow should treat external material as source data and keep task instructions separate. A page asking the agent to reveal credentials, run commands, or change its publication rules is not an authorized instruction from the business.
Limit the actions available during research. Reading and producing an evidence record are different from sending messages, purchasing services, or publishing changes. Put consequential actions behind an explicit review process appropriate to the organization. This separation is practical governance: it allows useful research without giving every retrieved page influence over business systems. It also makes failures easier to contain and investigate when a source is misleading or malicious.
A practical evaluation for marketing teams
Create a benchmark of ten research tasks drawn from the team's real workload. This is an illustrative evaluation size, not a scientific claim about the project. Include straightforward official announcements, a technical documentation question, a video transcript task, and a task where the source is unavailable. Compare the automated output with a human-reviewed reference record.
Measure correct source links, date accuracy, unsupported claims, missing qualifications, successful failure reporting, and time to an accepted output. Count correction time rather than stopping the clock when the agent produces text. A sensible acceptance rule is that no unsupported material claim reaches publication, while other tolerances are defined according to the task. If the tool fails at source preservation, fix that issue before increasing the number of channels or automating article production.
Healthcare and GCC applications
Karim could use the system to monitor public healthcare business announcements, platform product updates, and relevant open-source tools. Arabic and English outputs should be reviewed independently because correct extraction does not guarantee accurate translation. Technical terms, product availability, and local applicability can change meaning when compressed into a short summary.
Keep patient information and private clinical records outside a public-source research pilot. If future work involves institutional data, use a separate approved design with appropriate governance. For Gulf commercial research, test whether sources genuinely cover the intended geography instead of assuming a global feature is available locally. The most useful automation identifies those gaps and leaves them visible rather than filling them with a confident generalization.
From research assistant to publishing workflow
Do not connect retrieval directly to live publication. A reliable chain includes source collection, factual review, original writing, localized editing, image review, metadata validation, build checks, deployment, and live verification. The research layer can help with the first steps without owning the entire chain. Separating responsibilities protects the website when the upstream source or tool changes.
Keep a durable record of which stories were approved and which article versions were published. If a scheduled run fails, report the exact failed gate rather than treating a start time as completion. This discipline is especially relevant to a daily site: the system must produce useful content and verify that it is live, while preserving unrelated features such as article pinning. Research automation improves the inputs; it does not replace publication acceptance.
Karim's strategic decision
Start with a public-source evidence notebook for the marketing-led briefing and compare it with the current manual process. Use Agent Reach only where diagnostics and real tasks demonstrate value. Keep model choice, upstream dependencies, credentials, and human review explicit in the proposal. Avoid selling unrestricted internet access as though it were complete and reliable intelligence.
Expand when the pilot improves accepted-output time without reducing source quality or obscuring failures. If it works well for repositories and documentation but poorly for social channels, keep the useful portion and limit the rest. The strategic opportunity is a disciplined research service that produces traceable commercial insight. The repository is one possible enabling tool; the advantage comes from careful questions, maintained evidence, and a publishing process that can be trusted.
Comments
No published comments yet.