A team can produce a new campaign brief every week while repeating the same failed assumption. The useful question for an AI marketing assistant is therefore simple: can it explain what the team already tested, and why its next recommendation deserves attention?
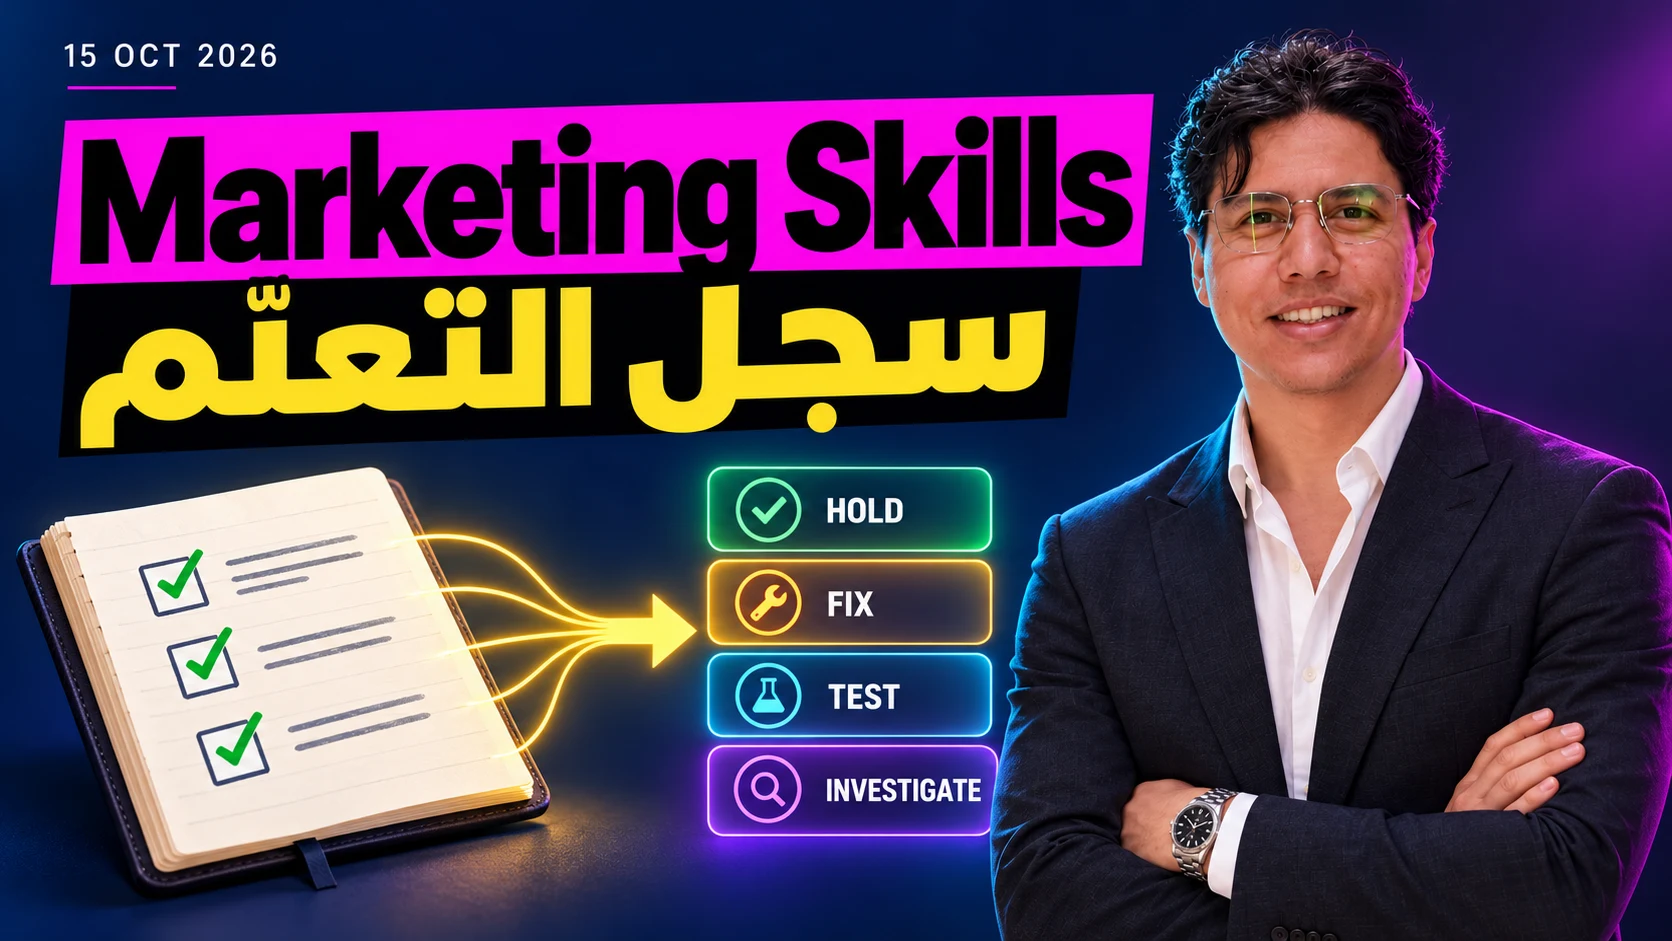
Marketing Skills’ 15 October 2026 updates make that question timely. The project’s official version history adds a learning ledger to product-marketing context, has copywriting and ads consult it, and introduces a weekly ad review ending in HOLD, FIX, TEST or INVESTIGATE. These are documented instruction changes, not demonstrated revenue gains. This analysis was prepared on 17 October; it is not a new-product launch announcement.
Our [October 5 introduction](/articles/marketingskills-open-source-ai-marketing-playbooks-2026) covered the library itself. The follow-up here concerns a narrower operating problem: how a marketing team can retain evidence between successive agent-assisted decisions.
The business cost of forgetting
Consider a fictional B2B software team that tested a discount-led message and attracted poorly qualified inquiries. A month later, an assistant proposes the same offer with a different headline. The copy looks new, but the commercial hypothesis is unchanged. Reviewing it consumes time, and running it again may consume budget without answering a new question.
A useful experiment record should make that repetition visible. It should state the audience, offer, channel, dates, measurement definition, observed result and remaining uncertainty. “Discounts do not work” is too broad. “This offer generated fewer sales-accepted opportunities among this audience during this test” is narrower and more useful. The distinction matters when a different audience or buying stage justifies trying a related idea again.
Build a record that can be challenged
Start with five fields: the decision, the supporting evidence, the conditions under which it applied, the owner who approved the conclusion, and a review date. Link to the actual report or approved aggregate export. Keep observations separate from interpretations and proposed actions.
For example, a fall in reported conversions could reflect weaker demand, a tracking defect or delayed CRM processing. Logging it as “creative fatigue” prematurely teaches the assistant the wrong lesson. An uncertain finding should remain uncertain until somebody checks the competing explanations.
Also define when a conclusion expires. Pricing, channel behavior, service capacity and audience composition can change. A record that never retires old assumptions can become a barrier to learning. At each review, ask whether the evidence still describes the current operating conditions.
Turn the weekly review into a decision
The four labels offer a useful structure, but their meaning needs to be agreed inside the team. The following interpretation is a proposed operating method, rather than a claim that the repository guarantees these outcomes.
- HOLD: evidence supports leaving the account unchanged until the next scheduled review. Record the next observation date and the condition that would reopen the decision.
- FIX: a specific, evidenced defect needs correction. Name the defect, the proposed change, the approver and a rollback condition.
- TEST: there is a new, bounded hypothesis. Specify the comparison, primary outcome, constraints and stopping rule before any launch.
- INVESTIGATE: the evidence is insufficient or contradictory. Assign the smallest check that could resolve the uncertainty.
The important output is the sentence beneath the label. “Investigate because yesterday’s CRM import is incomplete; operations will check it before a budget decision” is actionable. A colored status badge alone is not.
A controlled pilot for a healthcare marketing team
Imagine a Saudi company selling appointment-management software to healthcare providers. This is an illustrative B2B example, not a report of work carried out for a client. Choose one account and supply approved aggregate campaign and sales-stage data. Keep patient details, clinical information, credentials and identifiable contact records out of the exercise.
Prepare the human reviewer’s assessment first. Then ask the assistant to review the same evidence, identify relevant previous experiments and propose one decision with its confidence and missing information. Keep the pilot read-only: a recommendation should not alter ads, publish copy or contact a prospect.
For this example, a relevant business outcome might be the cost of a sales-accepted opportunity among providers that fit the product. Define that qualification consistently with sales. A cheaper form submission is not sufficient evidence to scale if the inquiries lack purchasing authority or operational fit.
For Arabic-English work, preserve the tested meaning as well as the headline. A benefit framed around administrative convenience may be interpreted differently from one framed around financial efficiency. Record the audience and language variant separately so a result from one message is not silently generalized to the other.
Measure the pilot before trusting the process
Use several review cycles and compare the assistant with the human baseline on the same cases. Track repeated hypotheses, unsupported claims, evidence links that fail inspection, reviewer correction time and decisions that change after missing data arrives. Do not set an arbitrary target that encourages the reviewer to accept a weak recommendation.
Commercial impact needs a later, properly designed experiment. Faster reporting alone cannot establish incremental revenue. If the pilot reduces review time while increasing factual errors, the workflow has not improved. If it catches repeated tests and exposes measurement gaps, those are useful intermediate outcomes to document without exaggeration.
Limits and a practical next step
A public instruction library cannot supply a company’s missing evidence or make a business decision accountable. The project’s repository provides reusable instructions; implementation still depends on the agent, tools, data quality and permissions. Review a fixed version before adopting changes, and keep approvals separate from recommendations.
The most useful next step is small: select one account, reconstruct three past experiments and run one parallel review. If the assistant cannot trace its recommendation to evidence, improve the record before increasing autonomy. A durable marketing advantage comes from preserving the reasoning behind tested decisions and making that reasoning available for scrutiny.
Sources and editorial scope
Primary verification: Marketing Skills’ version history dated 15 October 2026, especially entries 2.11.34 and 2.11.37, checked on 17 October. The workflow and examples above are original proposed applications, not measured results or claims of personal client experience. The cover is an original editorial illustration, not a product screenshot.
Karim Elganainy
Comments
No published comments yet.