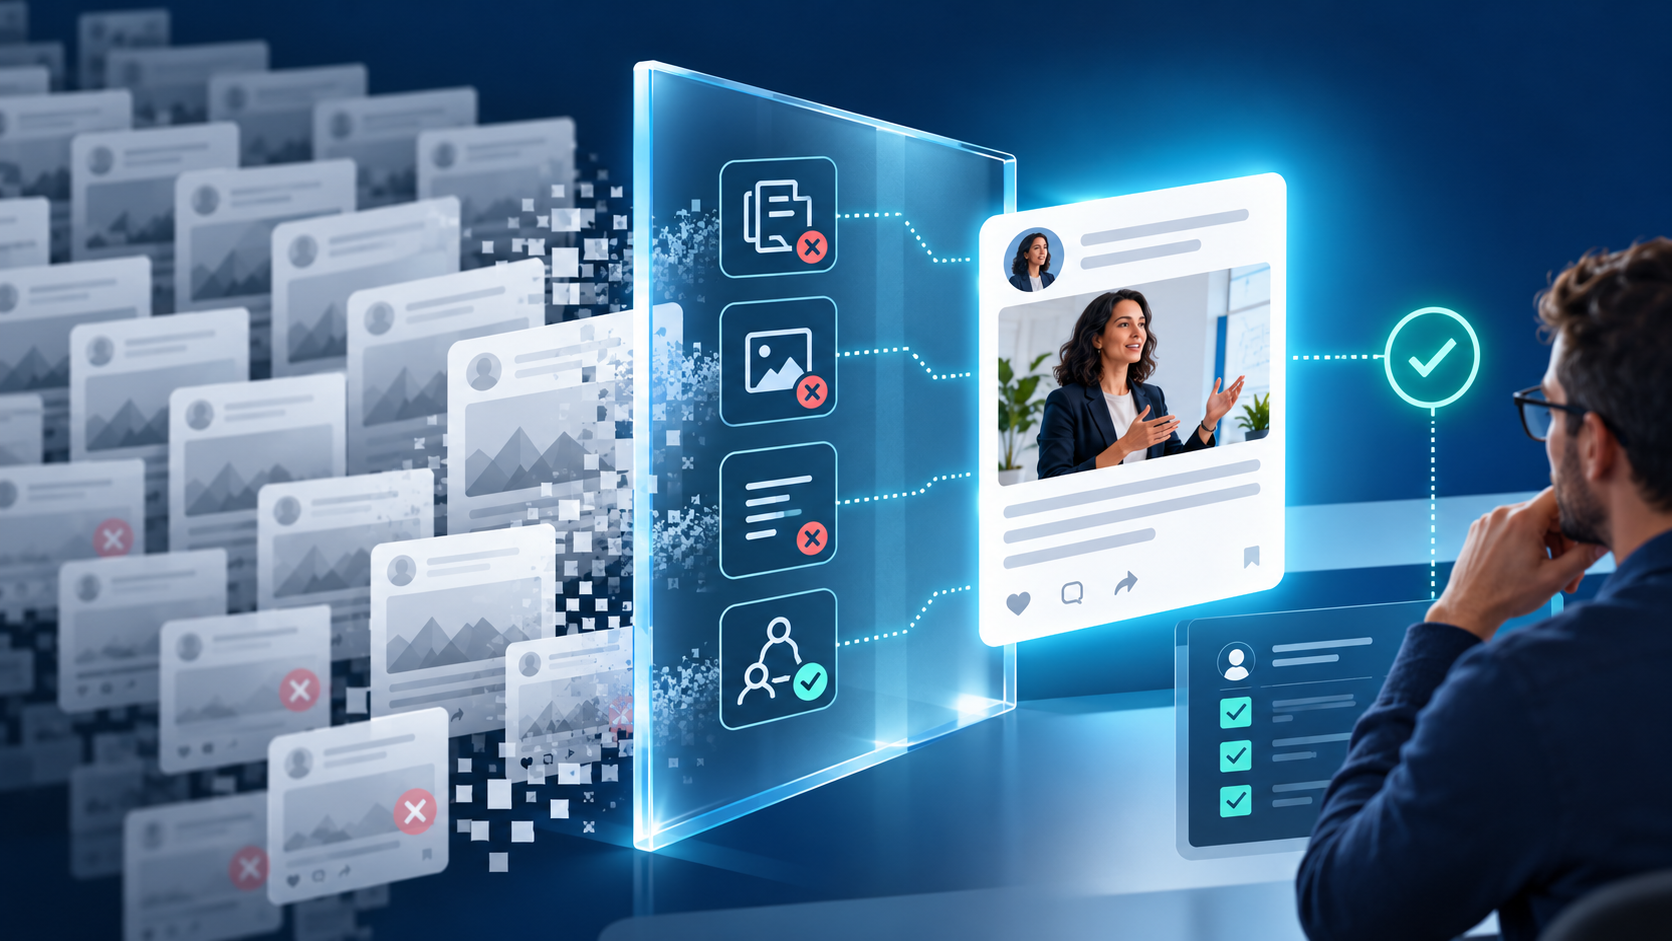
Original editorial illustration; it does not reproduce LinkedIn's interface or show a real moderation decision.
LinkedIn has explained more of the technical system it uses to reduce what it calls AI slop: low-value, repetitive or misleading material produced or amplified with automation. The important development is not a ban on AI-assisted writing. It is an enforcement architecture that tries to translate policy into detectable patterns, route uncertain cases to people, and reduce distribution when content fails quality or authenticity standards. In an official technical article, the company described large teacher models, smaller student models, LoRA adaptation, policy-specific agents and human review. Its newsroom overview puts the work in the context of a network the company says has 1.4 billion members.
LinkedIn also reported two performance claims: 94 percent precision for detection applied to posts beyond a member's network, and 40 percent fewer views for identified AI-slop content as of August 2026. These are company-reported operating metrics, not an independent audit. Precision describes the share of flagged examples judged positive under the company's labels; it does not reveal recall, the total prevalence of low-value content, or the business effect on an individual page. Social Media Today summarized the disclosure on 8 October in secondary coverage.
What the system is trying to distinguish
Generative tools can support research, translation, outlining and editing. The problem category is not simply text written with a model. It includes content that is mass-produced, duplicative, deceptive, ungrounded or optimized to simulate expertise without contributing useful information. A platform must apply broad policy language to billions of items, languages and contexts. That makes detection a classification and enforcement problem rather than a reliable AI-versus-human test.
For marketers, the distinction is crucial. Hiding tool use is not a durable strategy, and avoiding every AI tool does not guarantee quality. The safer objective is to publish material whose value can be verified: specific experience, attributable evidence, original analysis, accurate examples, appropriate disclosure and responsible editing. Those qualities help readers even when no moderation system is involved.
Teacher and student models create an operating hierarchy
LinkedIn describes using larger teacher models to interpret policy and label difficult examples, then training smaller student models to perform high-volume classification more efficiently. In general machine-learning practice, this teacher-student pattern can transfer behavior from a capable but expensive model to a faster model suited to production traffic. The company also mentions LoRA, a parameter-efficient adaptation technique that lets teams specialize models without retraining every parameter.
This does not mean an automated classifier makes every final decision. Policy-specific agents may gather signals and reason about particular rule families, while human specialists review ambiguous cases and feed corrections back into the system. The architecture resembles a risk funnel: cheap broad screening first, specialized analysis next, and scarce expert attention where uncertainty or impact is higher.
Why 94 percent precision is useful but incomplete
If a classifier has 94 percent precision under the reported evaluation, approximately 94 of every 100 items it flags are considered positive according to the reference labels in that test. It says nothing directly about how many undesirable items the classifier missed. That second dimension is recall. A conservative system can achieve high precision by flagging only obvious examples while leaving many borderline cases untouched.
The denominator and evaluation set also matter. LinkedIn specifies the figure for posts shown beyond a member's network, which suggests a distribution context rather than every post. The public article does not provide all details required to reproduce the result independently. Marketers should quote the number with that scope and identify it as a LinkedIn claim. They should not translate it into a 94 percent probability that any reduced post is AI-generated.
The 40 percent view reduction is an enforcement outcome
LinkedIn says views of identified AI-slop content fell 40 percent by August. That indicates the combined system is changing distribution, but it does not isolate which classifier, product rule or user behavior caused the decline. It also does not say that all ordinary posts lost or gained a particular amount of reach. The comparison period and underlying content volume affect interpretation.
Commercially, the direction matters more than treating 40 percent as a forecast. A platform protecting professional utility has an incentive to reduce incentives for mass publishing. Teams that rely on cheap, nearly identical thought-leadership posts face growing distribution and reputation risk. Teams with fewer, evidence-rich contributions may benefit if the feed contains less noise, but that benefit must be measured in their own results.
Audit the content supply chain, not only the final draft
Start by mapping how an idea becomes a published post. Record the source of the insight, research links, claims, model inputs, human editor, subject reviewer and approval. A polished final paragraph can still rest on an invented statistic or a copied argument. Conversely, a rough expert interview can contain original knowledge that deserves careful development. Quality control should preserve that source value through the workflow.
Set minimum evidence rules. Statistics need an attributable source, date, geography, denominator and context. A product claim should link to official documentation or be labeled as the company's claim. A personal observation should be described as experience, not population evidence. Keep research notes long enough to correct or defend the post. Do not paste confidential client or patient material into a general-purpose model.
Use AI for bounded tasks with named accountability
Define acceptable uses rather than issuing a vague permission or prohibition. A model may help cluster interview notes, suggest counterarguments, translate a reviewed draft, or check readability. It should not manufacture customer quotes, infer clinical facts, invent case-study results or make an unreviewed legal claim. Assign a human owner who can explain and approve the final content.
For translation, review the local version as an independent article. Arabic syntax, professional terminology and cultural assumptions can change meaning. For data analysis, verify calculations outside the model. For ideation, compare suggestions with internal evidence so the result does not become the same generic list that hundreds of other accounts can produce from an identical prompt.
Create an originality test editors can apply
Before publication, ask five questions. Does the post contain information that originates from our work or a clearly cited source? Does it explain a mechanism rather than merely state a conclusion? Does it acknowledge a limitation or trade-off? Can a reader take a specific, responsible action? Would the piece still be useful if the fashionable topic name were removed?
Score each answer zero, one or two. Require a minimum threshold and at least one two-point score for original evidence or analysis. This is not a platform rule; it is an internal control. Pair the score with a duplication check across the company's recent posts. Reusing a central position is reasonable, but repeating the same introduction, examples and list structure signals a production system optimized for volume rather than learning.
A six-week content quality experiment
Select two comparable topic families and publish at a sustainable cadence. In the treatment group, use the stronger process: expert source interview, primary evidence, explicit limitation, editor review and active replies. In the comparison group, keep the existing approved process without deliberately lowering quality. Measure impressions and engagement, but prioritize saves, substantive comments, profile visits from relevant roles, qualified connection requests, website visits and opportunities influenced.
Record production time and correction rate. Calculate substantive comments per 1,000 impressions so reach does not disguise quality. Track whether sales or recruitment teams reuse the post in real conversations. A content unit that earns moderate reach but repeatedly helps a qualified buyer may be more valuable than a viral generic post. Do not attribute a difference entirely to the new process if topic, author or distribution conditions changed.
Prepare for false positives and uneven enforcement
Any large classification system can misclassify legitimate content. Templates, recurring terminology and multilingual writing may look repetitive even when the underlying work is sound. Keep drafts, sources and approvals so a team can assess a sudden decline without guessing. Check account health and platform notices, but do not assume every reach fluctuation is a penalty. Organic distribution is variable for many reasons.
If a post is restricted or removed, use the formal appeal channel and provide concise evidence. Avoid publishing multiple near-identical replacements, which can compound the appearance of spam. Examine whether the content made its provenance clear and whether automation accidentally repeated language across employee accounts. Treat an incident as a workflow review, not an invitation to find evasive tricks.
GCC and bilingual implications
Arabic professional content may face smaller training sets, dialect variation, code-switching and specialized terminology. LinkedIn's public explanation does not provide language-level accuracy, so nobody should assume the 94 percent precision applies identically to Arabic or to every regional context. That uncertainty strengthens the case for careful human editing and retaining evidence, especially when posts combine Arabic, English brand names and technical expressions.
GCC brands can create defensible originality by using regional operating data they are permitted to share, interviews with local practitioners, and explanations of Saudi or UAE customer journeys. Translate the lesson, not just the sentence. A healthcare growth post can explain the gap between leads and attended appointments using an anonymized, permissioned method rather than recycling a global prompt about customer experience.
Healthcare and regulated brands carry extra risk
Low-value health content is not merely annoying; it can mislead decisions. Clinical statements should be reviewed by appropriately qualified professionals and linked to suitable evidence. Avoid generating before-and-after narratives, prevalence figures or treatment comparisons without sources. State geography, population and uncertainty. Separate education from diagnosis and do not invite personal health information in comments.
The publishing team also needs a correction protocol. Name the person who can pause a post, contact clinical leadership and issue a visible amendment. Track not only engagement but factual correction requests, inappropriate inquiries and escalation time. An efficient content operation that increases misinformation is not successful, even if the platform never flags it.
Karim's strategic decision
Karim can package an AI-assisted editorial governance sprint for professional and healthcare brands. The engagement would map the content supply chain, define permitted model tasks, create evidence and originality rubrics, train Arabic and English reviewers, and build a measurement dashboard around qualified response rather than raw volume. It should be positioned as operational quality and reputation protection, not a promise to defeat a classifier.
Proceed when the client has experts willing to contribute and leadership prepared to publish fewer, stronger pieces. Pause when the only goal is daily output at the lowest unit cost. After six weeks, expand only if substantive response, reuse in commercial conversations and correction performance improve without unsustainable production cost. LinkedIn's disclosure is a warning that platforms are investing in quality enforcement; the durable opportunity is to make the organization's knowledge genuinely worth distributing.
Comments
No published comments yet.